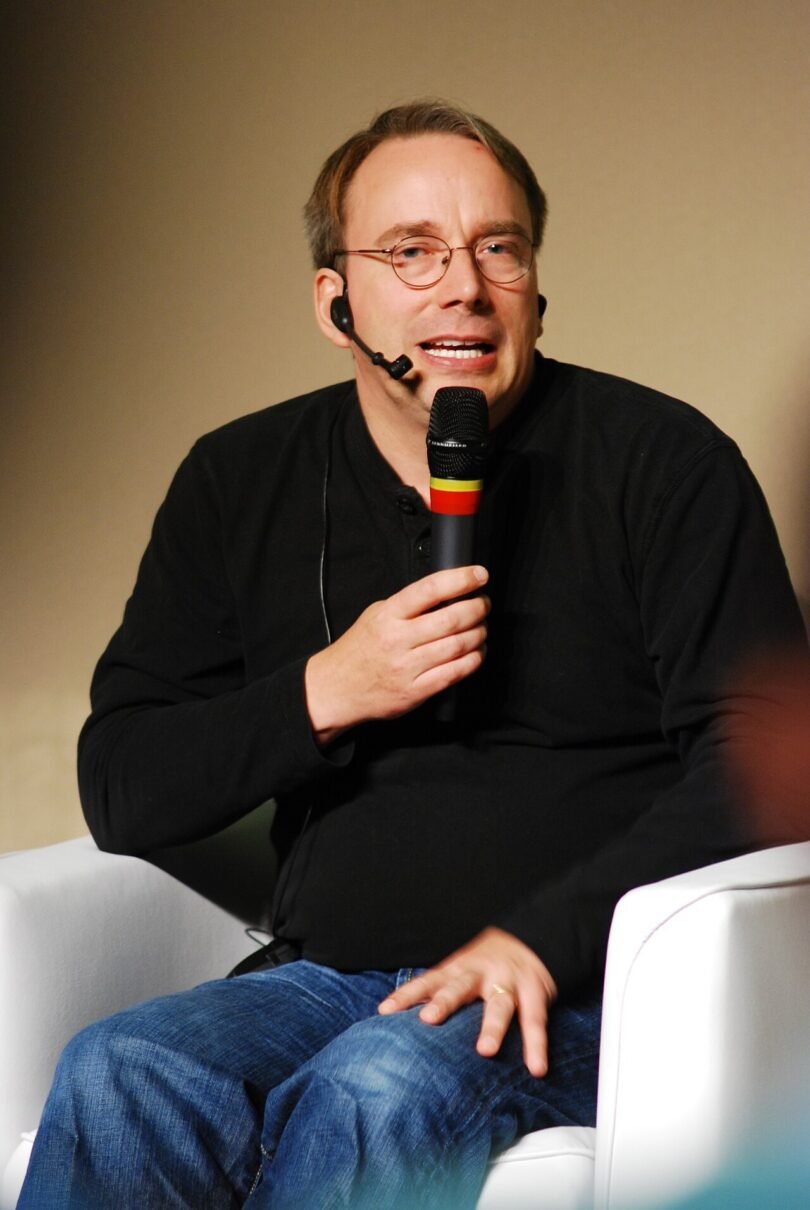

The Linux kernel is the most consequential piece of collaborative software ever written, and its creator has never been known for hype. So when reports describe Linus Torvalds improving kernel code with assistance from Claude Code — resolving a multithreaded file-read bottleneck and tripling throughput in the affected path — the story deserves attention precisely because of who is involved. The world’s most famous code reviewer used an AI coding assistant on the world’s most scrutinised codebase, and the result was a measurable, dramatic speedup.
Some context for the result itself: file reading at scale is one of the kernel’s oldest and most contested battlegrounds. When many threads read concurrently, they contend for shared bookkeeping — reference counts, locks, cache lines bouncing between cores — and throughput can collapse not because the hardware is slow but because the coordination is. Removing such a bottleneck can indeed multiply performance, which is why a threefold improvement is plausible rather than fantastical in this specific kind of fix.
Why This Bottleneck Mattered
Multithreaded read performance sits underneath almost everything a server does: web serving, databases, build farms, and the storage layers of cloud infrastructure. A bottleneck there is not an edge case; it is a tax on the world’s computing, paid billions of times a day. Kernel developers have attacked these contention points for decades with lock-free algorithms, per-CPU data structures and read-copy-update techniques, each fix harder than the last because the easy contention was engineered away long ago.
That history is what makes an AI-assisted breakthrough interesting. The remaining problems are the ones where the constraint is a subtle interaction — a cache line shared unnecessarily, a lock held slightly too long, a data layout that punishes a common pattern. Finding them requires reading enormous amounts of code with total recall of how the pieces interact, which happens to be a fair description of what large language models are good at when a expert is steering them.
The Reviewer Stays in Charge
Anyone imagining Torvalds pasting generated code into the kernel misunderstands both the man and the process. The kernel’s development model, documented at kernel.org, is built on public review, maintainer hierarchies and an almost institutional scepticism toward unproven change. An AI assistant in that environment is a power tool in the hands of the person least likely to misuse it: useful for exploring hypotheses, drafting candidate restructurings and checking interactions across files, with every line still subject to the same merciless review as any human contribution.
That division of labour — machine proposes, expert disposes — is the pattern emerging across serious software engineering. The productivity gains are real but asymmetrical: they are largest for the developers who need them least, because only deep expertise can tell a brilliant suggestion from a plausible catastrophe.
A Signal to Every Engineering Organisation
Torvalds has historically been a lagging indicator with leading significance: he adopts tools late, publicly, and only when they survive contact with real work. His visible use of an AI assistant on performance-critical kernel code will do more to normalise AI-assisted systems programming than a hundred vendor keynotes. Teams maintaining large C codebases — operating systems, databases, embedded platforms — will read the story as permission to experiment in the areas they previously considered too sensitive for generated code.
What It Does Not Prove
One bottleneck fixed is not a methodology validated. Kernel performance work is littered with fixes that tripled a microbenchmark and changed nothing in production, and the community will judge this change the way it judges all changes: by the patch, the measurements and the regressions that do or do not appear. The honest headline is narrower and still significant — an expert, using an AI assistant as an instrument, found and fixed a real problem unusually fast.
The Larger Story
The Maintainers’ View From Below
One level down from the headlines, kernel maintainers will process this story the way they process everything: by reading the patch. The subsystem’s other contributors will want to know which invariant changed, what the lock ordering looks like now, and whether the fix’s benefits survive on architectures other than the one it was developed on. Thoroughness in that review is not pedantry; it is the mechanism by which the kernel has remained trustworthy for thirty years, and an AI-assisted patch receives no exemption from it — which is, in the end, the strongest argument that AI assistance and kernel standards can coexist.
The episode also lands in a live policy debate inside open source. Projects worldwide are drafting rules for AI-generated contributions: disclosure requirements, licensing provenance, accountability when generated code infringes or fails. The kernel’s culture suggests the shape of the eventual settlement — the tool is irrelevant, the submitter is responsible — and a high-profile success under exactly that rule will influence how dozens of other projects write theirs.
For the broader industry, the takeaway is calibration. AI did not write the kernel a new feature while its creator watched; it helped the most qualified person alive interrogate a hard problem faster. Technologies earn trust in serious engineering one such episode at a time, and this one counts for more than most.
There is a pleasing symmetry in the episode. The kernel that runs most of the world’s AI infrastructure was improved by that same AI — a feedback loop between the tool and the platform it stands on. Whether or not this particular fix becomes famous, the loop is now closed and visible. The craft of kernel development is not being automated; it is being amplified, starting, appropriately, at the very top.